The 5 Steps to an Effective Disaster Recovery Plan in Practice
When a critical application becomes unavailable, the quality of a disaster recovery plan is not measured by the volume of documentation it contains, but by the time it takes to restore service and the actual conditions under which service is restored. The five steps of an effective disaster recovery plan (DRP) transform a recovery plan from an intention into an operational, governed, and verifiable system. They require collaboration among business units, the IT department, cybersecurity, risk management, and senior leadership, because a DRP does not merely cover infrastructure—it protects the ability to deliver an essential service.
The Disaster Recovery Plan (DRP) is a component of the overall business continuity framework. While the Business Continuity Plan (BCP) addresses the continuity of critical business operations as a whole, the Recovery Plan (RPA) specifically outlines the restoration of systems, applications, data, and technical resources following a major disruption. This distinction is crucial: a system can be technically restored without the business actually being able to resume its operations.
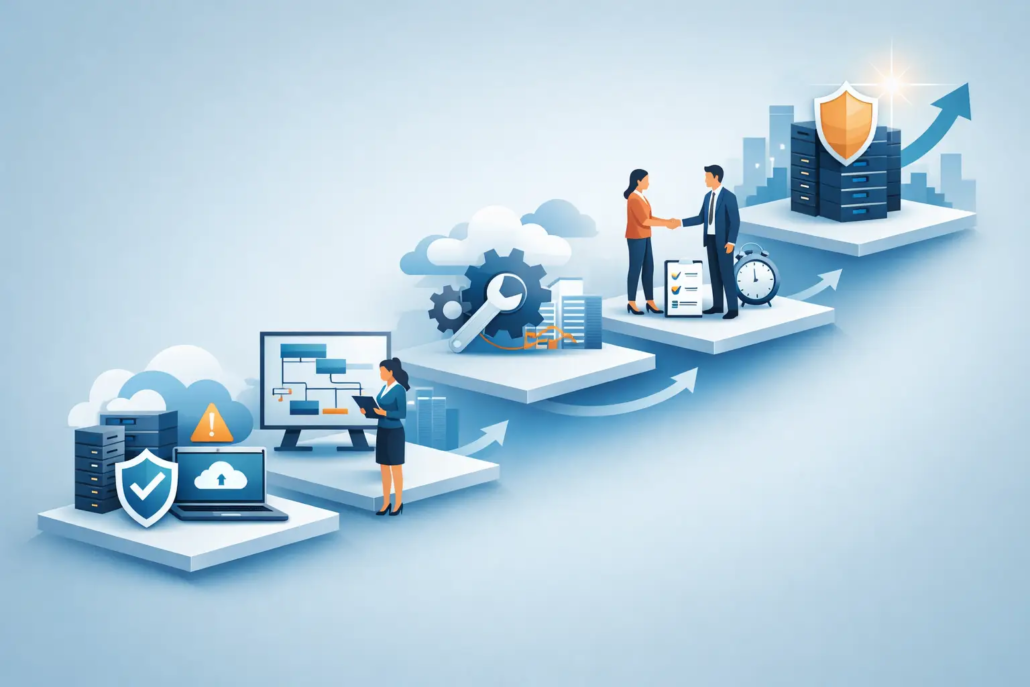
The 5 Steps to an Effective Disaster Recovery Plan
1. Define the scope based on business impacts
An effective disaster recovery plan begins with a factual understanding of the business activities that need to be protected. You should not start with the available tools, nor should you replicate an existing architecture in a disaster recovery document. The starting point is the Business Impact Analysis (BIA), which identifies critical processes, their dependencies, the consequences of downtime, and the acceptable level of disruption over time.
This analysis must link each priority activity to the components necessary for its implementation: applications, databases, data flows, identities, workstations, networks, service providers, hosting sites, and key skills. Indirect dependencies are often the ones that most compromise recovery. A production application may be restarted but remain unusable if the authentication service, a banking data flow, a monitoring interface, or a SaaS provider remains unavailable.
The framework must also specify the scenarios under consideration. A data center outage, cloud provider downtime, data corruption, a cyberattack involving encryption, a network outage, or a power outage do not all require the same response. A plan designed solely for a physical disaster will be insufficient in the face of ransomware that has compromised backups and privileged accounts. The level of coverage depends on the organization’s risk profile and its regulatory or contractual obligations.
2. Set consistent and balanced recovery objectives
Recovery objectives translate business needs into operational requirements. The RTO, or maximum recovery time, specifies the acceptable time frame for restoring a service. The RPO, or maximum allowable data loss, defines the acceptable point of recovery. These metrics should not be chosen arbitrarily or imposed uniformly across the entire information system.
A four-hour RTO and an RPO close to zero require costly technical, contractual, and human resources: redundancy, replication, monitoring, expedited procedures, on-call staff, and frequent testing. Conversely, accepting a recovery time of several days may be appropriate for a non-critical support tool. The challenge is to document these trade-offs, have the assumptions validated by business owners, and demonstrate that the chosen strategy is proportionate to the impacts.
These objectives must be supplemented by recovery criteria. Recovery does not simply mean making an application accessible. It is necessary to specify the required reference data, the minimum volumes to be processed, security checks, functional validations, and the conditions for returning to normal operation. In some cases, a recovery in degraded mode is preferable to a prolonged wait for a fully restored service.
3. Develop a realistic recovery strategy
A disaster recovery strategy outlines the resources deployed to achieve defined objectives. It may rely on restorable backups, a disaster recovery site, cloud infrastructure, cross-zone replication, fallback environments, or a combination of these measures. The choice is never purely technological: it involves costs, internal expertise, vendor contracts, sovereignty constraints, and the ability to operate under pressure.
For each critical component, the recovery method, restart order, prerequisites, and checkpoints must be identified. The target architecture must also account for the risk of propagation. In a cybersecurity context, quickly restoring a compromised environment does not constitute a recovery. Isolated backups, clean environments, data integrity verification, and controlled management of privileged access are required before any system is returned to production.
The strategy must address capabilities that are rarely taken into account in technical plans: recovery bandwidth, available licenses, procurement lead times, access to password vaults, storage resources, processing capacity, and team availability. A backup solution advertised as available within a few hours must be able to prove this under anticipated operational conditions, including when a service provider is simultaneously called upon by multiple clients.
4. Establish formal procedures that can be implemented and clear governance
A disaster recovery plan (DRP) is activated in a context of uncertainty, often with reduced staff and incomplete information. The procedures must therefore be precise without becoming unreadable. They define the activation criteria, roles, escalation procedures, recovery actions, technical checks, business validation, and communication protocols.
Each critical action must be assigned to a role, with a designated alternate. It is best to clearly distinguish between the decision-making team—which assesses the incident and determines priorities—and the implementation teams—which restore services. Crisis management and internal or external communication must be coordinated with the Disaster Recovery Plan (DRP), without blurring responsibilities. A decision to resume operations can have consequences for security, compliance, customer relations, and the organization’s reputation.
Operational documents benefit from including information that can be put to immediate use: contact information, access to tools, dependencies, startup sequences, validated commands or scripts, acceptance criteria, and report templates. However, they must remain secure and accessible in the event that the usual information system is unavailable. A plan hosted solely on the environment it is intended to restore has an obvious weakness.
5. Test, measure, and maintain the system
An untested disaster recovery plan is merely a hypothesis. Drills verify not only technical recovery but also the availability of personnel, the quality of procedures, the relevance of identified dependencies, and decision-making capacity. They frequently reveal simple but critical issues: an expired service account, an obsolete procedure, an incomplete backup, an incorrect restart command, or an unavailable provider.
Testing can proceed in stages. A literature review helps verify the plan’s consistency; a tabletop exercise evaluates coordination; a technical test verifies targeted recovery; and a switchover exercise provides more comprehensive validation. The level of ambition must be tailored to the criticality, the acceptable risk, and the organization’s ability to withstand a controlled disruption. For the most critical services, only tests that closely mimic real-world conditions can validate compliance with the RTO and RPO.
After each exercise or incident, a formal debriefing is essential. Deviations must be prioritized, assigned to responsible parties, and tracked until they are resolved. Maintenance of the disaster recovery plan must also be triggered by significant changes: architectural changes, cloud migration, a new service provider, business process transformation, changes in security requirements, or the departure of a key expert.
Making the PRA a managed resilience mechanism
Maturity does not depend on the existence of a plan, but on the ability to demonstrate that it is aligned with business impacts, financially viable, actionable, and regularly tested. Simple metrics can support this management process: coverage rate for critical services, adherence to the testing schedule, open issues, achievement of RTOs and RPOs, or updating of procedures following major changes.
Business continuity standards, particularly ISO 22301, provide a useful framework for embedding these practices within a sustainable governance structure. They do not replace operational expertise, but they help structure responsibilities, documentation, and continuous improvement. The professionalization of teams therefore remains a key factor: when faced with a major incident, methodology and preparation make the difference between a reactive recovery and a controlled recovery.
The next PRA review can thus become a concrete decision-making exercise: for each critical service, is the organization able to demonstrate—through test results—how it would resume operations, with what data, and under whose authority?
This post is also available in:


